RAG và Vectorize: chatbot “nhớ tài liệu” giải thích dễ hiểu RAG and Vectorize: teaching a chatbot your documents, explained simply RAG and Vectorize: teaching a chatbot your documents, explained simply
Mô hình AI không “nhớ” PDF của bạn — RAG tìm đoạn liên quan trong Vectorize rồi đưa vào prompt. Workers AI sinh câu trả lời có căn cứ hơn đoán mò. Models do not “remember” your PDFs — RAG finds relevant chunks in Vectorize and adds them to the prompt. Workers AI generates answers grounded in context instead of guessing. Models do not “remember” your PDFs — RAG finds relevant chunks in Vectorize and adds them to the prompt. Workers AI generates answers grounded in context instead of guessing.
Retrieval Augmented Generation (RAG) Retrieval Augmented Generation (RAG) Retrieval Augmented Generation (RAG)
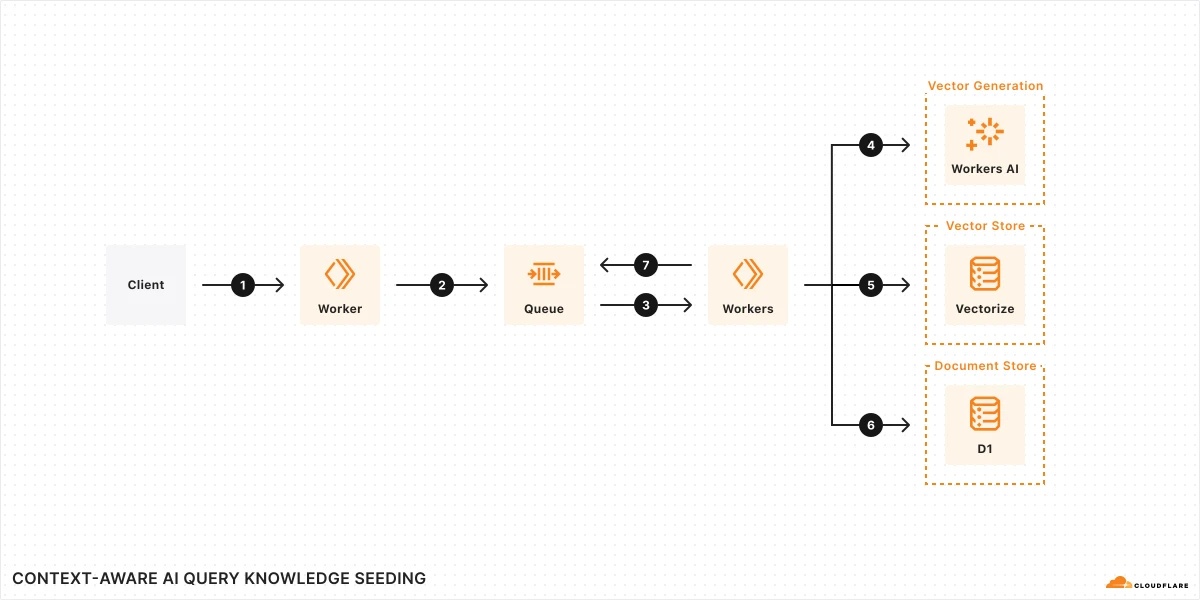
RAG kết hợp retrieval (Vectorize/KV) với Workers AI để chatbot trả lời chính xác hơn — seeding knowledge và query path tách biệt. RAG combines retrieval with generative models for better text. It uses external knowledge to create factual, relevant responses, improving coherence and accuracy in NLP tasks like chatbots. RAG combines retrieval with generative models for better text. It uses external knowledge to create factual, relevant responses, improving coherence and accuracy in NLP tasks like chatbots.
Thuật ngữ: Concepts: Concepts: RAG · Vectorize · Workers AI · Knowledge seeding · Embeddings
Sơ đồ chính thức ↗ Official diagram ↗ Official diagram ↗ · AI Artificial Intelligence (AI) Artificial Intelligence (AI)
Vì sao chatbot thường “bịa” — và RAG giải quyết thế nào? Why chatbots often “make things up” — and how RAG helps Why chatbots often “make things up” — and how RAG helps
Mô hình ngôn ngữ lớn (LLM) dự đoán từ tiếp theo dựa trên dữ liệu đã học — không tự đọc file nội bộ của công ty bạn trừ khi bạn đưa nội dung vào ngữ cảnh. Hỏi “chính sách nghỉ phép năm 2026” mà model không thấy tài liệu HR, nó có thể trả lời nghe hợp lý nhưng sai — gọi là hallucination. Large language models (LLMs) predict the next token from training data — they do not read your internal files unless you put content in context. Ask about “2026 PTO policy” without HR docs in context and the model may sound plausible but wrong — hallucination. Large language models (LLMs) predict the next token from training data — they do not read your internal files unless you put content in context. Ask about “2026 PTO policy” without HR docs in context and the model may sound plausible but wrong — hallucination.
RAG (Retrieval-Augmented Generation) thêm bước: (1) chuyển câu hỏi thành vector tìm kiếm, (2) lấy vài đoạn tài liệu liên quan nhất từ kho tri thức, (3) gửi đoạn đó kèm câu hỏi vào LLM để sinh câu trả lời. Model vẫn sáng tạo ngôn ngữ, nhưng bám sát nguồn bạn cung cấp. RAG (Retrieval-Augmented Generation) adds steps: (1) turn the question into a search vector, (2) fetch the most relevant document chunks from your knowledge store, (3) send those chunks plus the question to the LLM. The model still writes naturally but stays closer to sources you provide. RAG (Retrieval-Augmented Generation) adds steps: (1) turn the question into a search vector, (2) fetch the most relevant document chunks from your knowledge store, (3) send those chunks plus the question to the LLM. The model still writes naturally but stays closer to sources you provide.
Trên blog.cloudflare.com, các bài về Vectorize và Workers AI thường demo pattern này trên edge: ít phụ thuộc GPU tự quản, latency thấp hơn so với vòng qua một server trung tâm duy nhất. Phù hợp hub AI Security & Adoption khi bạn muốn thử RAG có kiểm soát. On blog.cloudflare.com, Vectorize and Workers AI posts often demo this pattern at the edge: less self-managed GPU ops, lower latency than routing everything through one central server. It fits the hub’s AI Security & Adoption track when you want controlled RAG experiments. On blog.cloudflare.com, Vectorize and Workers AI posts often demo this pattern at the edge: less self-managed GPU ops, lower latency than routing everything through one central server. It fits the hub’s AI Security & Adoption track when you want controlled RAG experiments.
Retrieval Augmented Generation (RAG) Retrieval Augmented Generation (RAG) Retrieval Augmented Generation (RAG)
RAG kết hợp retrieval (Vectorize/KV) với Workers AI để chatbot trả lời chính xác hơn — seeding knowledge và query path tách biệt. RAG combines retrieval with generative models for better text. It uses external knowledge to create factual, relevant responses, improving coherence and accuracy in NLP tasks like chatbots. RAG combines retrieval with generative models for better text. It uses external knowledge to create factual, relevant responses, improving coherence and accuracy in NLP tasks like chatbots.
Thuật ngữ: Concepts: Concepts: RAG · Vectorize · Workers AI · Knowledge seeding · Embeddings
Sơ đồ chính thức ↗ Official diagram ↗ Official diagram ↗ · AI Artificial Intelligence (AI) Artificial Intelligence (AI)
Embedding là gì — “tóm tắt số” của đoạn văn What are embeddings — numeric summaries of text What are embeddings — numeric summaries of text
Embedding biến đoạn text thành dãy số (vector) sao cho đoạn nghĩa gần nhau có vector gần nhau trong không gian toán học. Bạn không cần hiểu công thức — chỉ cần biết: cùng chủ đề → dễ tìm thấy nhau khi search. An embedding turns text into a number array (vector) so semantically similar passages sit close together in math space. You do not need the formula — just know: same topic → easier to find via search. An embedding turns text into a number array (vector) so semantically similar passages sit close together in math space. You do not need the formula — just know: same topic → easier to find via search.
Quy trình seed tài liệu: cắt PDF/wiki thành chunk (đoạn nhỏ), chạy model embedding (Workers AI có model cho việc này), lưu vector + metadata (tiêu đề, URL, ngày) vào Vectorize. Khi user hỏi, embed câu hỏi, Vectorize trả top-k chunk gần nhất. Seeding docs: split PDFs/wiki into chunks, run an embedding model (Workers AI offers models for this), store vectors plus metadata (title, URL, date) in Vectorize. On user questions, embed the query; Vectorize returns the top-k nearest chunks. Seeding docs: split PDFs/wiki into chunks, run an embedding model (Workers AI offers models for this), store vectors plus metadata (title, URL, date) in Vectorize. On user questions, embed the query; Vectorize returns the top-k nearest chunks.
Chọn kích thước chunk quan trọng: quá dài → nhiễu; quá ngắn → mất ngữ cảnh. Thử 300–800 token mỗi chunk cho tài liệu kỹ thuật; chỉnh theo loại nội dung. Metadata giúp lọc theo ngôn ngữ, sản phẩm, hoặc quyền truy cập sau này. Chunk size matters: too long adds noise; too short loses context. Try 300–800 tokens per chunk for technical docs; tune per content type. Metadata later helps filter by language, product, or access rights. Chunk size matters: too long adds noise; too short loses context. Try 300–800 tokens per chunk for technical docs; tune per content type. Metadata later helps filter by language, product, or access rights.
Vectorize trong kiến trúc Cloudflare — nối Workers AI Vectorize in Cloudflare’s architecture — wiring Workers AI Vectorize in Cloudflare’s architecture — wiring Workers AI
Vectorize là vector database managed trên Cloudflare: bạn không tự cài Pinecone/Postgres pgvector trên VPS. Worker gọi binding Vectorize để insert và query; Workers AI binding để embed và generate — mọi thứ trong cùng ecosystem, billing và region edge quen thuộc. Vectorize is a managed vector database on Cloudflare: you do not self-host Pinecone or pgvector on a VPS. A Worker calls Vectorize bindings to insert and query; Workers AI bindings to embed and generate — same ecosystem, familiar edge billing and regions. Vectorize is a managed vector database on Cloudflare: you do not self-host Pinecone or pgvector on a VPS. A Worker calls Vectorize bindings to insert and query; Workers AI bindings to embed and generate — same ecosystem, familiar edge billing and regions.
Luồng runtime điển hình: POST /chat → Worker embed câu hỏi → Vectorize.query → ghép chunk vào system prompt (“chỉ trả lời dựa trên nguồn sau”) → Workers AI @cf/meta/llama hoặc model bạn chọn → trả JSON cho frontend. Có thể thêm AI Gateway để log, rate limit, và chặn prompt injection. Typical runtime flow: POST /chat → Worker embeds question → Vectorize.query → stitch chunks into system prompt (“answer only from sources below”) → Workers AI @cf/meta/llama or your chosen model → return JSON to frontend. Add AI Gateway for logging, rate limits, and prompt-injection guards. Typical runtime flow: POST /chat → Worker embeds question → Vectorize.query → stitch chunks into system prompt (“answer only from sources below”) → Workers AI @cf/meta/llama or your chosen model → return JSON to frontend. Add AI Gateway for logging, rate limits, and prompt-injection guards.
Không lưu secret API key trong trình duyệt: toàn bộ RAG chạy Worker. Frontend chỉ gửi câu hỏi đã xác thực user. Đọc bài AI Gateway và Workers AI trên hub nếu bạn lo chi phí hoặc lạm dụng endpoint. Never store API secrets in the browser: run all RAG in a Worker. The frontend only sends authenticated questions. Read the AI Gateway and Workers AI posts on this hub if you worry about cost or endpoint abuse. Never store API secrets in the browser: run all RAG in a Worker. The frontend only sends authenticated questions. Read the AI Gateway and Workers AI posts on this hub if you worry about cost or endpoint abuse.
Vectorize phù hợp tri thức vừa và nhỏ đến trung bình — FAQ sản phẩm, handbook nội bộ, release notes. Dữ liệu cực lớn hoặc cần hybrid search phức tạp có thể cần kiến trúc mở rộng (AI Search, pipeline ETL) — bước sau khi prototype RAG cơ bản chạy ổn. Vectorize fits small-to-medium knowledge — product FAQs, internal handbooks, release notes. Very large corpora or heavy hybrid search may need expanded architecture (AI Search, ETL pipelines) — a step after your basic RAG prototype works. Vectorize fits small-to-medium knowledge — product FAQs, internal handbooks, release notes. Very large corpora or heavy hybrid search may need expanded architecture (AI Search, ETL pipelines) — a step after your basic RAG prototype works.
Thực hành an toàn và chất lượng — không chỉ “cắm là chạy” Safe practice and quality — not just “plug and play” Safe practice and quality — not just “plug and play”
Chất lượng: đánh giá câu trả lời với bộ câu hỏi mẫu; ghi lại chunk nào được retrieve; tinh chỉnh prompt “không biết thì nói không biết”. Bảo mật: lọc tài liệu nhạy cảm trước khi index; tách index theo tenant; dùng Access hoặc auth trước Worker chat. Quality: evaluate answers with a sample question set; log which chunks were retrieved; tune prompts to say “I don’t know” when unsure. Security: filter sensitive docs before indexing; separate indexes per tenant; use Access or auth before the chat Worker. Quality: evaluate answers with a sample question set; log which chunks were retrieved; tune prompts to say “I don’t know” when unsure. Security: filter sensitive docs before indexing; separate indexes per tenant; use Access or auth before the chat Worker.
Chi phí: embedding hàng loạt khi ingest + mỗi câu hỏi (embed + generate). Cache câu hỏi phổ biến; giới hạn độ dài context; AI Gateway budget alerts. Tuân thủ: ghi rõ nguồn trích dẫn cho user — tăng tin cậy và debug. Cost: bulk embedding on ingest plus per question (embed + generate). Cache frequent questions; cap context length; AI Gateway budget alerts. Compliance: show citation sources to users — builds trust and aids debugging. Cost: bulk embedding on ingest plus per question (embed + generate). Cache frequent questions; cap context length; AI Gateway budget alerts. Compliance: show citation sources to users — builds trust and aids debugging.
Lộ trình hub: hoàn thành Workers AI intro → thử Vectorize quickstart trong docs → thêm Gateway → đọc cheatsheet bảo vệ AI. Một demo RAG nhỏ (10 trang markdown) học nhiều hơn đọc mười bài lý thuyết. Hub path: finish Workers AI intro → try Vectorize quickstart in docs → add Gateway → read the AI protection cheatsheet. One small RAG demo (10 markdown pages) teaches more than ten theory-only articles. Hub path: finish Workers AI intro → try Vectorize quickstart in docs → add Gateway → read the AI protection cheatsheet. One small RAG demo (10 markdown pages) teaches more than ten theory-only articles.
Hình minh họa Cloudflare Cloudflare visuals Cloudflare visuals
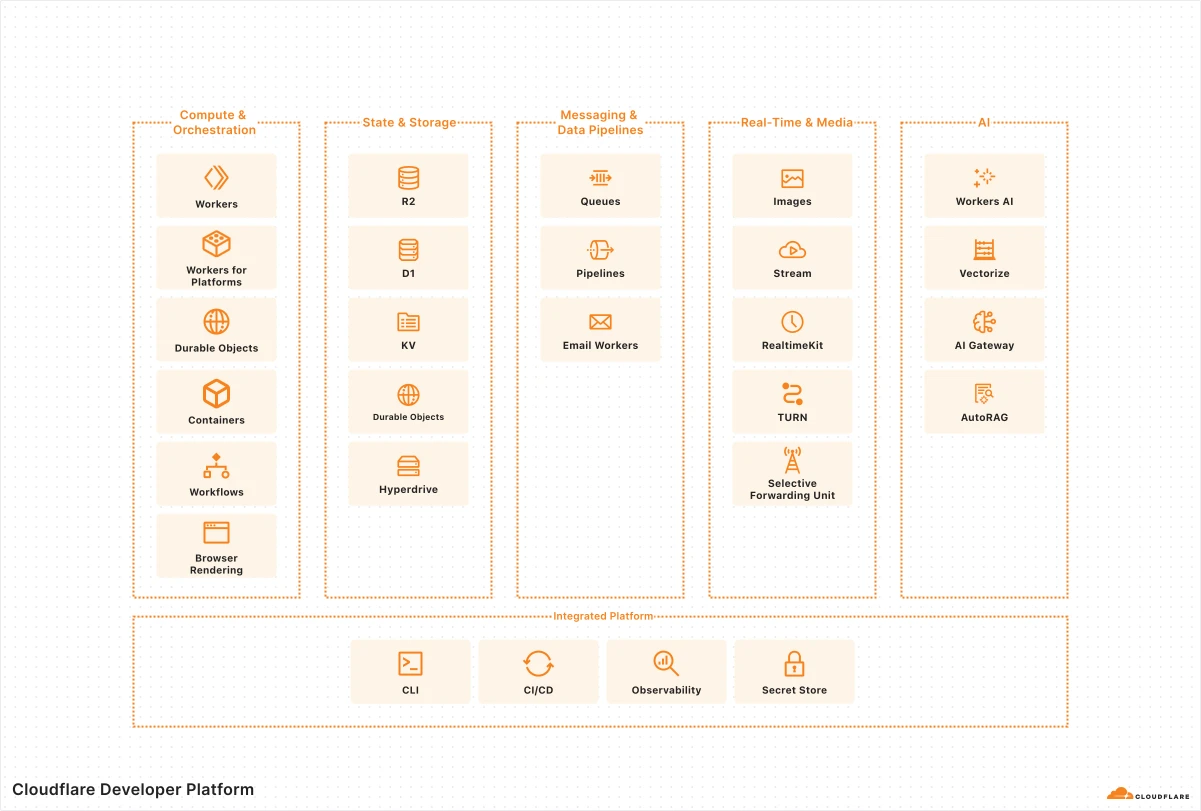
Sơ đồ Reference Architecture chính thức và (khi có) ảnh Dashboard — giúp đối chiếu khi học. Official Reference Architecture diagrams and (when available) Dashboard screenshots — useful while you learn. Official Reference Architecture diagrams and (when available) Dashboard screenshots — useful while you learn.

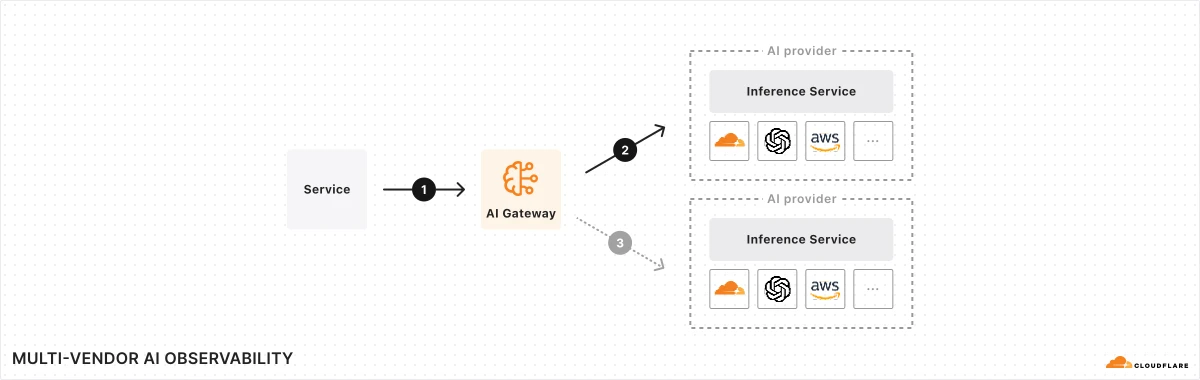
Kiến trúc AI kết hợp (composable) Composable AI architecture Composable AI architecture
Ứng dụng AI có thể dựng end-to-end trên Cloudflare, hoặc gắn từng dịch vụ vào hạ tầng và dịch vụ bên ngoài. The architecture diagram illustrates how AI applications can be built end-to-end on Cloudflare, or single services can be integrated with external infrastructure and services. The architecture diagram illustrates how AI applications can be built end-to-end on Cloudflare, or single services can be integrated with external infrastructure and services.
Thuật ngữ: Concepts: Concepts: Workers AI · AI Gateway · External LLM · Composable stack
Sơ đồ chính thức ↗ Official diagram ↗ Official diagram ↗ · AI Artificial Intelligence (AI) Artificial Intelligence (AI)
Câu hỏi thường gặp Frequently asked questions Frequently asked questions
RAG có thay fine-tune model không? Does RAG replace fine-tuning? Does RAG replace fine-tuning?
Thường bổ sung cho nhau. RAG cập nhật tri thức nhanh bằng cách đổi tài liệu index — không cần train lại model. Fine-tune khi bạn cần giọng điệu hoặc format đặc thù sâu. Nhiều sản phẩm bắt đầu bằng RAG trước. They usually complement each other. RAG updates knowledge fast by changing the index — no full retrain. Fine-tune when you need deep tone or format. Many products start with RAG first. They usually complement each other. RAG updates knowledge fast by changing the index — no full retrain. Fine-tune when you need deep tone or format. Many products start with RAG first.
Vectorize khác KV/D1 thế nào? How is Vectorize different from KV/D1? How is Vectorize different from KV/D1?
KV/D1 lưu key-value hoặc SQL — tìm theo khóa hoặc query có cấu trúc. Vectorize tối ưu tìm kiếm ngữ nghĩa theo vector gần nhau — phù hợp “câu hỏi tự nhiên → đoạn liên quan”, không phải SELECT WHERE id = 5. KV/D1 store key-value or SQL — lookup by key or structured query. Vectorize optimizes semantic nearest-neighbor search — fit for “natural question → relevant passage,” not SELECT WHERE id = 5. KV/D1 store key-value or SQL — lookup by key or structured query. Vectorize optimizes semantic nearest-neighbor search — fit for “natural question → relevant passage,” not SELECT WHERE id = 5.
Có thể dùng tiếng Việt trong RAG không? Can RAG work with Vietnamese? Can RAG work with Vietnamese?
Có — chọn model embedding và LLM hỗ trợ đa ngôn ngữ; chunk và metadata ghi rõ locale; đánh giá bằng câu hỏi tiếng Việt thật. Chất lượng phụ thuộc model và chất lượng tài liệu nguồn. Yes — pick multilingual embedding and LLM models; tag chunks with locale metadata; evaluate with real Vietnamese questions. Quality depends on models and source document quality. Yes — pick multilingual embedding and LLM models; tag chunks with locale metadata; evaluate with real Vietnamese questions. Quality depends on models and source document quality.
Học tiếp trên hub (on-page backlinks) Keep learning on this hub (on-page links) Keep learning on this hub (on-page links)
- Workers AI (trang sản phẩm) Workers AI (product page) Workers AI (product page)
- Lộ trình AI Security & Adoption AI Security & Adoption track AI Security & Adoption track
- Use case: xây ứng dụng AI Use case: build AI applications Use case: build AI applications
- Cheatsheet bảo vệ AI AI protection cheatsheet AI protection cheatsheet
- Lộ trình Developer Platform Developer Platform track Developer Platform track
- Sản phẩm: Vectorize Product: Vectorize Product: Vectorize
Nguồn tham khảo (blog.cloudflare.com) Sources (blog.cloudflare.com) Sources (blog.cloudflare.com)
Nội dung được viết lại để dễ hiểu hơn; luôn đọc bài gốc trên blog.cloudflare.com và docs chính thức khi cần chi tiết kỹ thuật hoặc cập nhật mới nhất. Content is rewritten for clarity; always read the original posts on blog.cloudflare.com and official docs for technical detail or the latest updates. Content is rewritten for clarity; always read the original posts on blog.cloudflare.com and official docs for technical detail or the latest updates.